 VectorNine Systems
TokenForge: Modular AI Inference Architecture
Unlocking scalable, open-weight LLM execution through multi-enclosure PCIe star topologies. Engineered by VectorNine Systems Inc.

The Monolithic Bottleneck
Edge AI deployments are constrained by the physical, thermal, and bandwidth limits of traditional hardware chassis. Scaling local, multi-agent AI pipelines across standard consumer or server boards introduces unacceptable latency, Power Delivery Network (PDN) instability, and restricted bus bandwidth. The future of edge compute requires a decentralized physical layer.
The TokenForge Architecture
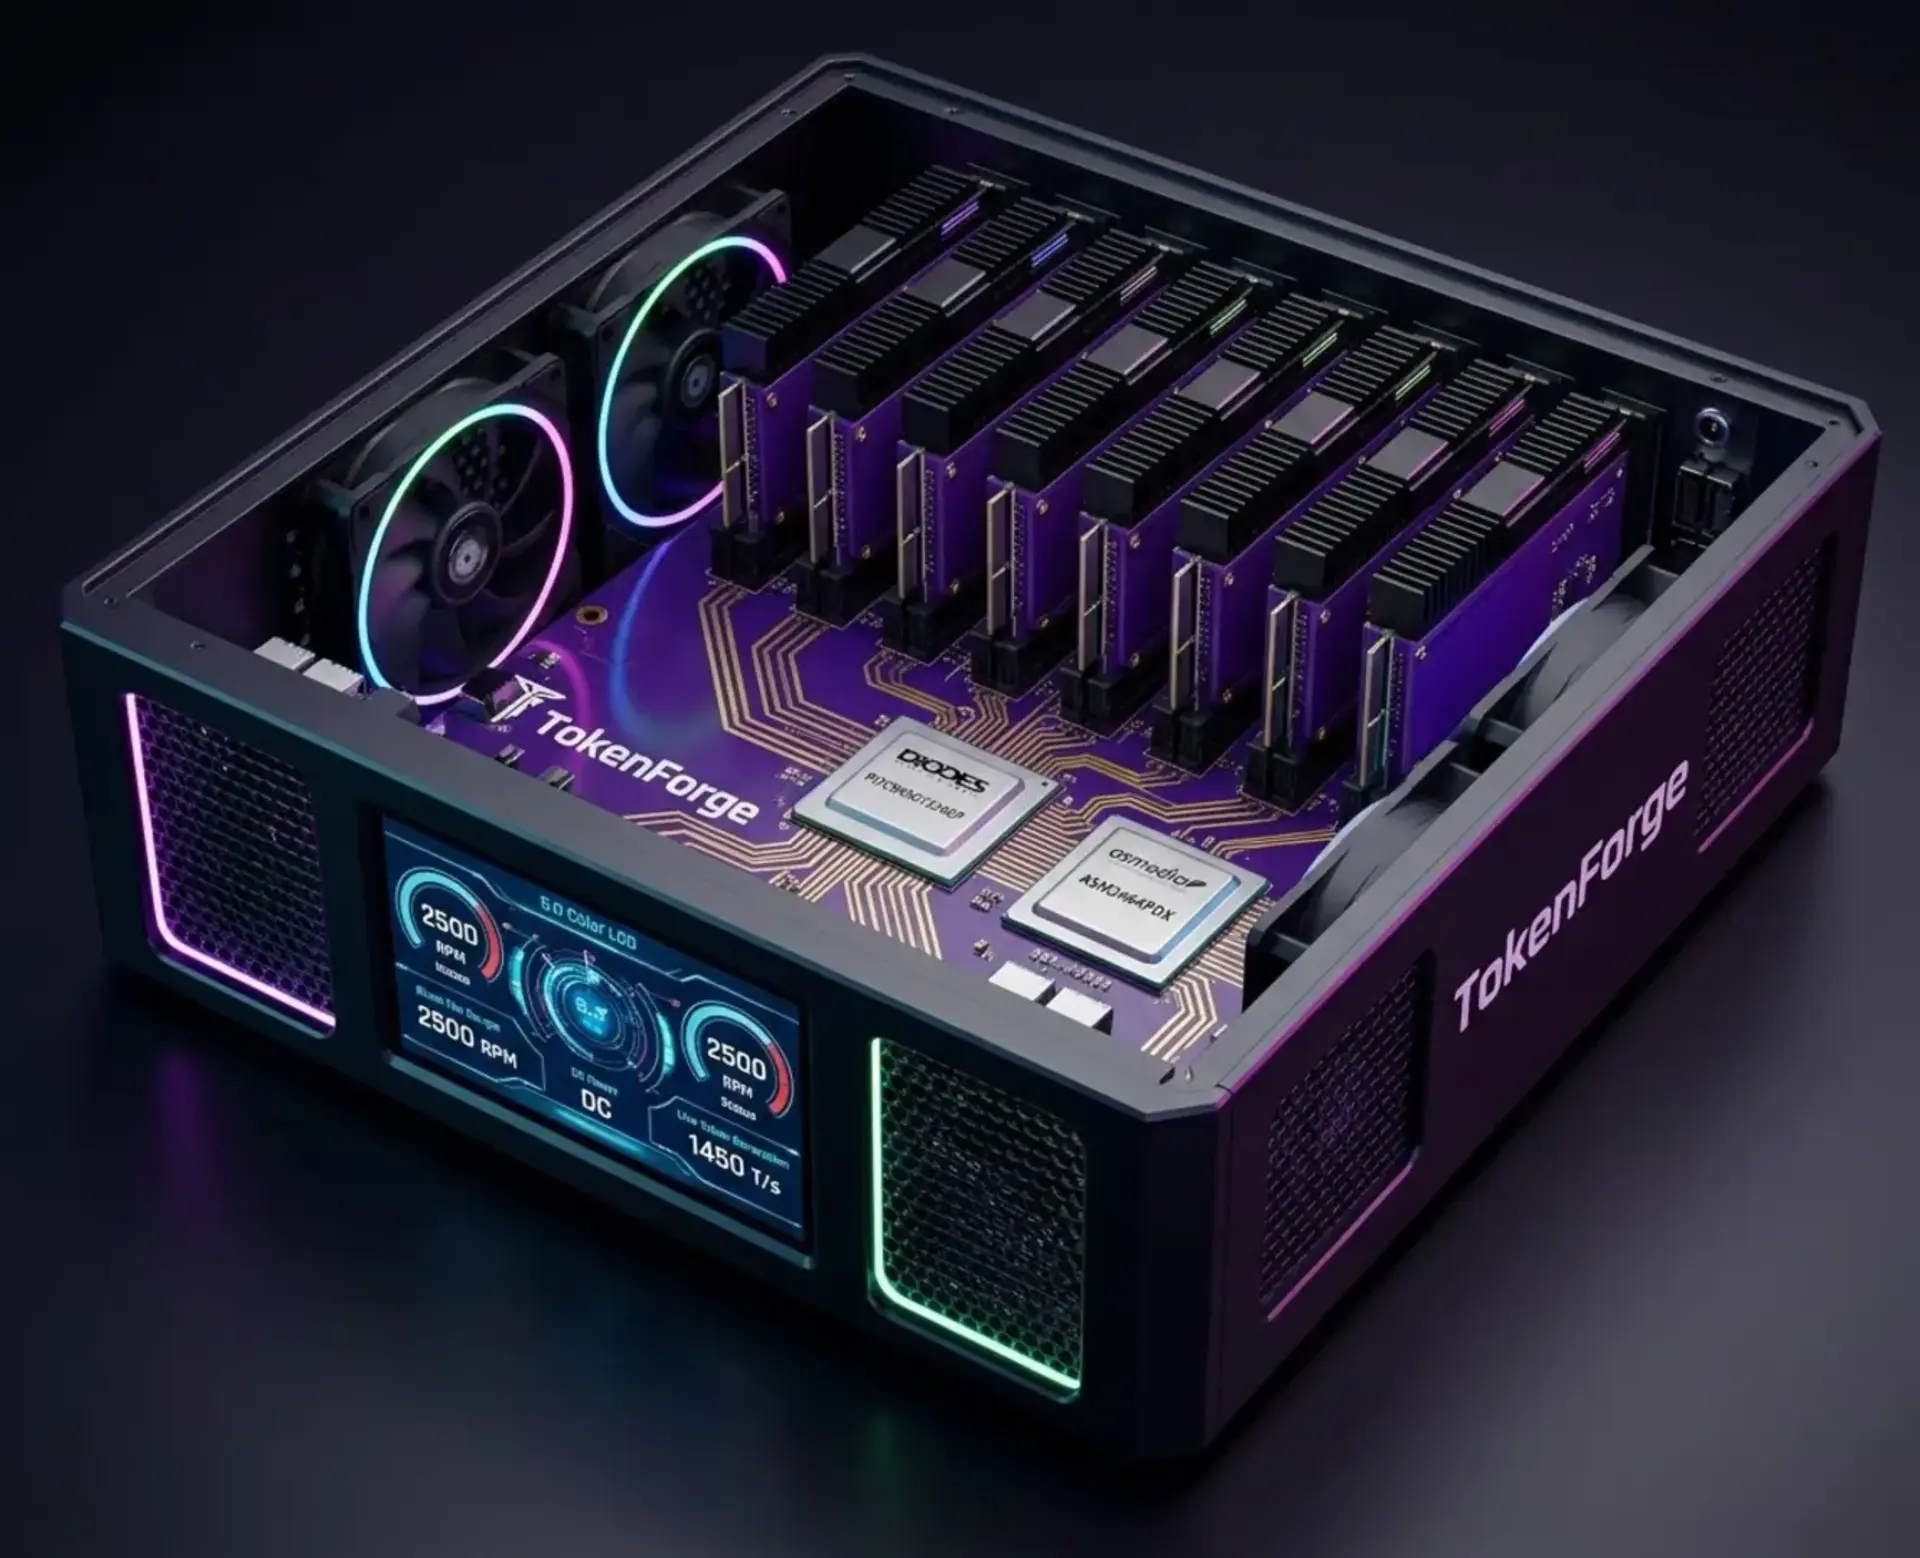
TokenForge decentralizes AI inference. By leveraging a custom multi-enclosure star topology, our PCIe backplane isolates power domains while maintaining high-bandwidth, low-latency data pathways. This architecture allows for the seamless clustering of NPUs, SoCs, and accelerators without chassis-imposed thermal throttling or structural limits.
Hardware & Stack Integration
- Interconnect Topology: Strictly managed PCIe lane bifurcation distributed across modular, multi-enclosure nodes.
- Power Integrity: Custom, high-tolerance PDN architecture featuring isolated voltage rails to eliminate cross-enclosure power sag under heavy AI workloads.
- Pipeline Agnostic: Native hardware optimization for deploying local LLMs, multi-agent frameworks, and vector retrieval pipelines using vLLM, Ollama, and ChromaDB.
- Scalability: Designed to support high-end discrete architectures, including RTX ADA generation hardware, across a unified backplane.
Engineering Trajectory
VectorNine Systems is currently in the active prototyping and architectural validation phase. We are conducting rigorous physical testing of our custom Power Delivery Network (PDN) and PCIe switching topologies in preparation for initial pilot intake and scaled manufacturing.
